Nagent vs Sprinklr
Compare a social publishing, intelligence or care operating layer with Nagent, the multiplayer AI platform for growth teams.
Sprinklr is a social publishing, intelligence or care operating layer, priced at a quoted rate. Nagent is multiplayer AI for growth teams: agent teams for marketing, sales and CX in one shared workspace, from $29.99 a month, with autonomy earned on approved work. Choose by the work the social lead and customer-care owner needs done and the controls around it.
The decision this comparison supports
Sprinklr and Nagent should be compared around the work a growth team wants to complete, the people who remain accountable and the evidence available for each offer. This guide treats Sprinklr as a social publishing, intelligence or care operating layer. Nagent is the multiplayer AI platform for growth teams: AI agent teams for marketing, sales and CX that work with people in one shared workspace. Neither category label is a performance result; the useful comparison is the work, the controls and the evidence.
Sprinklr is broader than a social-writing tool. Its strongest comparison is a coordinated enterprise customer operation, where migration and existing workflow ownership matter. The useful next step is to choose one bounded workflow and require both proposals to describe the same inputs, outputs, permissions, service commitments and human responsibilities. A demonstration can then answer a concrete buying question instead of rewarding whichever vendor has the more expansive vocabulary.
For this category, the recommended decision owner is the social lead and customer-care owner. The target result is quality engagement and timely, accurate customer responses. That definition deliberately includes acceptance and ownership. Faster generation is valuable only when people can trust, use and maintain the resulting work. A successful pilot should show both the work completed and the effort required to supervise it.
A custom engagement can include implementation and ongoing operations that a software subscription leaves to the buyer. Conversely, an established specialist or suite can bring repeatable workflows that would be expensive to rebuild. Compare those delivery boundaries explicitly. Buying flexibility that nobody has time to operate can be as costly as buying a standardized workflow that cannot handle a material exception.
What the sources establish
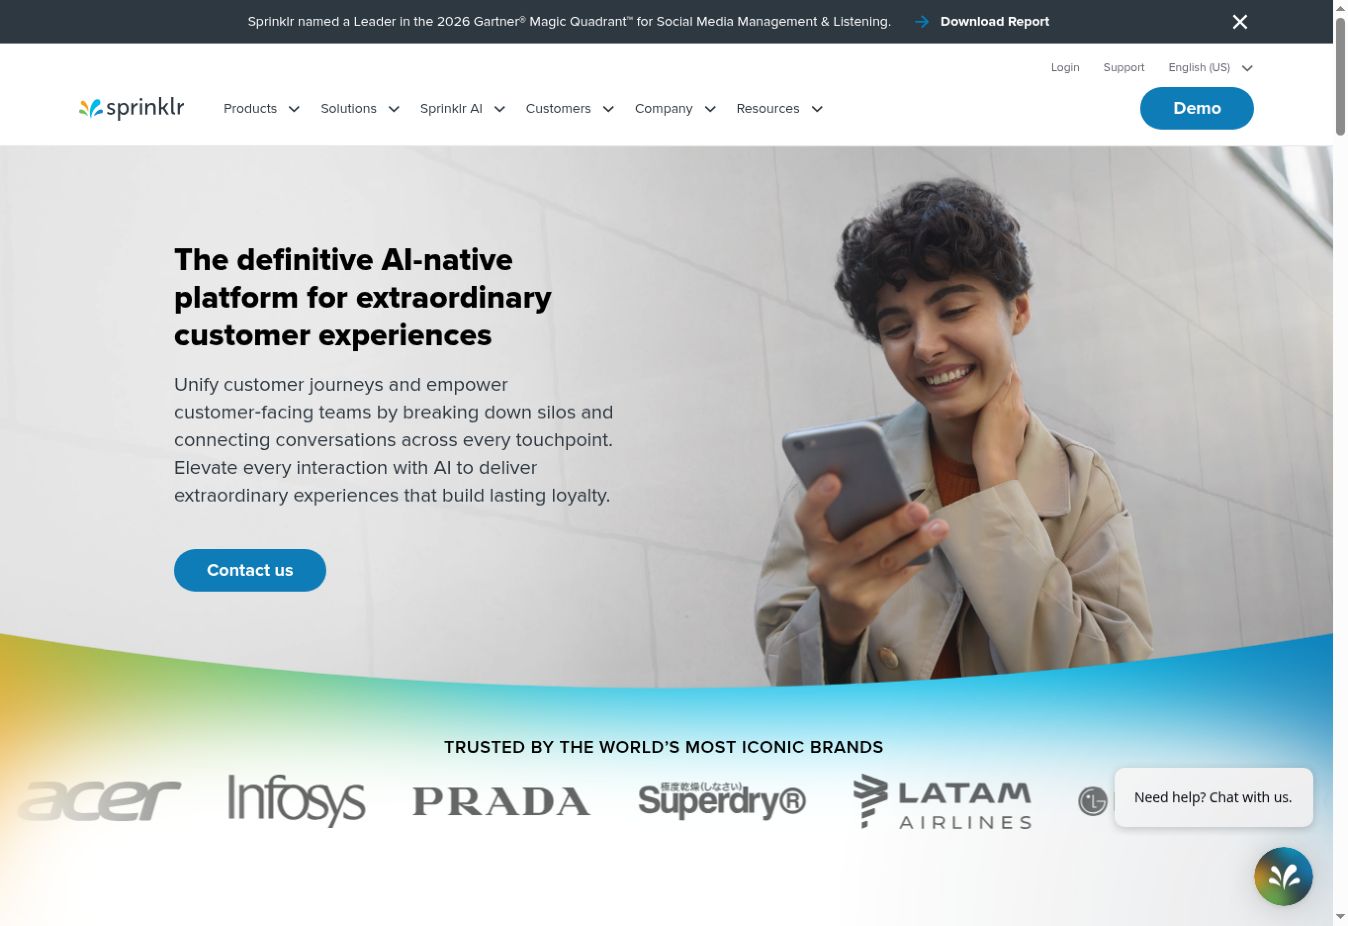
Sprinklr connects social marketing, listening, service and customer experience. Its current positioning includes agentic workflows and human–AI collaboration across customer-facing teams. [V1] [V2]
These are findings about published product descriptions and commercial packaging. They verify what the reviewed source says; they do not independently verify the product’s reliability, the breadth of a deployment or the truth of every outcome claim. The source register identifies the pages used so that a buyer can inspect the original context and ask for a current contractual answer.
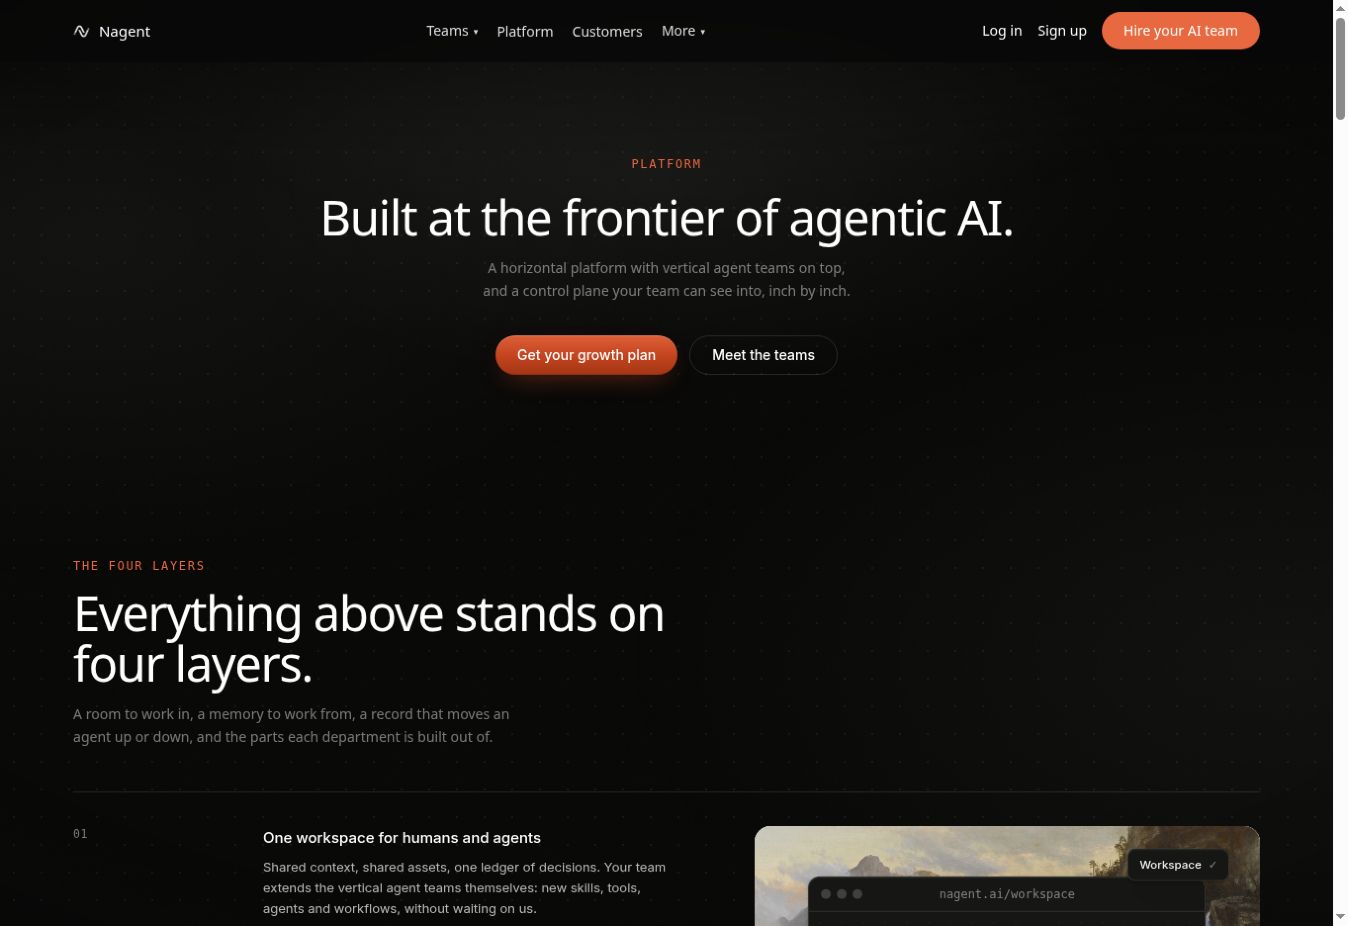
Nagent runs a shared workspace for people and agents, Smriti memory that every agent reads, Karma performance records built from each agent's KPIs and governance history, and composable skills, tools, agents and workflows. 17 ready-to-install agents ship today: one super agent, 8 function specialists and 8 industry strategists. Agents run on 19 model providers and 61 models and connect to 998 tools. The marketplace lists 58 published agents in all. 4 patents filed, 3 published. Autonomy is earned: every agent starts at a named level and is promoted on approved work, never automatically. SOC 2 Type II and ISO 27001 programmes underway; tenant isolation, RBAC, append-only audit and private VPC available today. [N1] [N2]
The evidence has three practical levels. Documented statements cover what an official page currently describes. Vendor claims include performance, reliability, autonomy and customer-result assertions that have not been independently audited here. Editorial analysis covers the implications, proposed tests and buying judgments in this guide. A missing fact is shown as unverified, not silently converted into a negative feature claim.
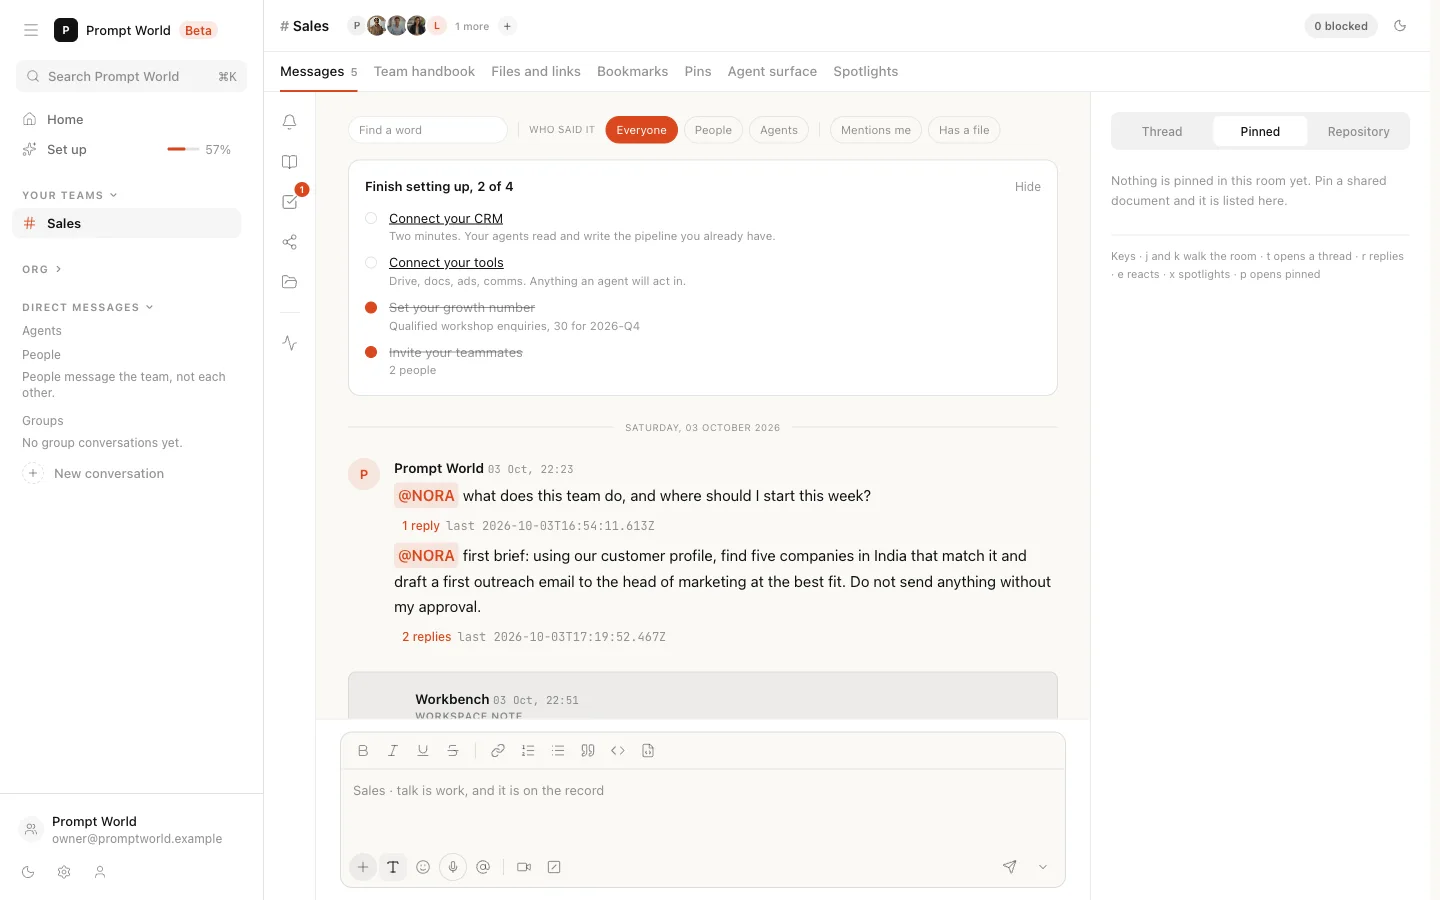
Screenshots in this research library show public source pages. They help preserve the vendor’s positioning and visible product presentation at the time of capture. They are not authenticated product tests and do not prove that the illustrated workflow was run by this research team. No synthetic dashboard is used as evidence of a vendor’s capability.
Operating model and category fit
Social tools already coordinate people through calendars, approvals and inboxes. Adding an AI writer is not the same as adding shared intelligence or governed autonomy. The strongest comparison asks how brand context, customer context and publishing authority stay aligned when work moves from a planner to an agent and then to a public channel.
Nagent ships ready-to-install agent teams into a shared operating process and adds Nagent AI Labs, forward deployed engineers and Growth Pods where custom delivery is wanted. A statement of work should still say which parts are installed, which are configured and which are built for you, and attach acceptance evidence to each material promise.
Sprinklr should be evaluated using the same discipline. A broad platform may need workflow design; a specialist may need integration; a suite may need additional modules; an infrastructure service may need a complete application. None of those dependencies automatically makes a product inferior. They determine the skills, budget and ownership required to make the purchase successful.
The comparison can also end in a complementary architecture. One system might own customer records, another supply a specialized capability, and a shared workspace coordinate the people and decisions. If that is the result, define one owner for each piece of state and one owner for each external action. Two agents that both believe they own the same customer workflow can create duplication, inconsistent messages and difficult incident analysis.
Preserve a written decision record as the evaluation develops. State the business problem, the alternatives considered, the evidence still missing and the assumptions behind the recommendation. This is particularly useful in a fast-changing market: a new feature or revised price should update the relevant assumption without forcing the team to repeat the entire debate. Give every unresolved requirement an owner and a next evidence step. A question that affects deployment should not disappear into an informal sales conversation. Close it with a demonstrated result, a contractual commitment or an explicit decision to accept the limitation within a narrower scope.
At a glance
| Dimension | Nagent | Sprinklr |
|---|---|---|
| Operating role | Multiplayer AI platform: agent teams and people in one shared workspace | a social publishing, intelligence or care operating layer |
| Commercial basis | Solo $29.99 per month ($19.99 on annual billing), Team $299 ($199), Business $1,499 ($999), Enterprise by quote. Credits per month are the unit of agent work; Growth Pods add human experts on Business and Enterprise. | Enterprise quote. No current numerical suite price verified; modules and service scope vary. |
| Evidence | Nagent runs a shared workspace for people and agents, Smriti memory that every agent reads, Karma performance records built from each agent's KPIs and governance history, and composable skills, tools, agents and workflows. 17 ready-to-install agents ship today: one super agent, 8 function specialists and 8 industry strategists. Agents run on 19 model providers and 61 models and connect to 998 tools. The marketplace lists 58 published agents in all. 4 patents filed, 3 published. | Sprinklr connects social marketing, listening, service and customer experience. Its current positioning includes agentic workflows and human–AI collaboration across customer-facing teams. |
| Critical demonstration | Can two colleagues join the same live agent task, change its direction, inspect the memory it used, approve or reject an action and export the audit trail? Nagent demonstrates this in a team room. | Can one region’s agent access another brand’s inbox, content library or customer records? |
Screenshots and source context
Specific published product behaviour
Social publishing approval within a larger suite
Sprinklr’s Social Publishing product describes scheduling and engagement across more than 30 social and messaging channels with custom approval workflows. Its help center lists AI features that may be enabled on request, so a suite-level AI label does not mean every function is available in a specific contract. A social publishing approval covers channel content; it is not proof of governance across every third-party agent or all customer records.
For a multi-brand growth team, test a draft that crosses brand, region and legal review before posting, then change a campaign claim and see whether approval resets. Measure the actual seat, module, approval and reporting entitlement in an enterprise quote. Sprinklr may own the publishing endpoint while a separate human–agent workspace coordinates the wider campaign.
Primary sources: Official Social Publishing platform ↗ · Official social AI feature availability ↗
Published documentation and public illustrations; account behaviour was not independently tested.
Promoted use cases and three evaluation scenarios
Sprinklr promotes the following areas in the reviewed material. [V1]
- Publish and govern social content
- Listen to customer and market signals
- Route and resolve omnichannel service work
The scenarios below are editorial test designs. They are not claims that either vendor already supports every step. A candidate may appropriately declare a scenario outside its product scope; record that boundary instead of inventing a capability.
1. A multi-brand content calendar
Create a week of content for two brands with distinct voices and channel constraints. Ask an agent to reuse a common campaign insight without mixing logos, claims or permissions. Require an editor to approve each brand’s content and confirm that a later scheduling change preserves that approval history.
Measure brand leakage, accepted posts, scheduling accuracy and reviewer time. Use the same input packet and acceptance rule for both candidates. Retain the original result, the reviewer’s corrections and the final accepted output so that a second evaluator can understand the conclusion. If the vendor supplies implementation help, record that time separately from the buyer’s own work.
End the exercise with a change or exception, not only a happy-path demonstration. Ask the responsible person to inspect the current state, explain the next permitted action and either approve, redirect or stop it. This exposes whether context and control survive the moment when a real operating process stops being predictable.
2. Public conversation to human care
Introduce a customer complaint beneath a campaign post. The workflow should identify the issue, avoid inventing an account-specific answer and route the customer to an appropriate human or authenticated channel. Test whether marketing and support see the same context without exposing private information publicly.
Measure routing accuracy, inappropriate replies and time to a useful handoff. Use the same input packet and acceptance rule for both candidates. Retain the original result, the reviewer’s corrections and the final accepted output so that a second evaluator can understand the conclusion. If the vendor supplies implementation help, record that time separately from the buyer’s own work.
End the exercise with a change or exception, not only a happy-path demonstration. Ask the responsible person to inspect the current state, explain the next permitted action and either approve, redirect or stop it. This exposes whether context and control survive the moment when a real operating process stops being predictable.
3. Listening becomes an editorial decision
Give the system a mixture of useful signals, noisy mentions and a sudden spike. Ask it to explain what changed and propose a response. Require the team to distinguish a genuine customer theme from a temporary engagement anomaly before altering the content calendar.
Measure evidence quality, false alarms and accepted changes to the publishing plan. Use the same input packet and acceptance rule for both candidates. Retain the original result, the reviewer’s corrections and the final accepted output so that a second evaluator can understand the conclusion. If the vendor supplies implementation help, record that time separately from the buyer’s own work.
End the exercise with a change or exception, not only a happy-path demonstration. Ask the responsible person to inspect the current state, explain the next permitted action and either approve, redirect or stop it. This exposes whether context and control survive the moment when a real operating process stops being predictable.
Shared context: what must actually travel
For this comparison, the essential context includes a brand, channel and conversation. The first test is whether the system can identify the source, owner and freshness of that information. A long conversation history is not sufficient if the agent cannot tell an approved fact from an obsolete draft, or if a new participant cannot understand which version influenced a decision.
Separate context into source material, current business state, instructions and remembered learning. These have different update rules. A customer record may change immediately; a brand guide may require a formal release; a useful lesson may need a reviewer before it becomes reusable memory. The platform should make these distinctions visible enough that operators can correct the right object rather than repeatedly rewriting prompts.
Ask Sprinklr and Nagent to handle a deliberate contradiction: one current source and one plausible but outdated source. Require the output to identify the conflict and show which source controls the decision. Then revoke access to the current source and repeat the relevant step with a different authorized participant. The purpose is to inspect permission behaviour, not to demand disclosure of hidden model reasoning.
A useful memory demonstration includes correction and deletion. Add an inaccurate assumption to the test context, correct it with a named human decision, and check whether future tasks still rely on the old assumption. Record the scope of the correction: one task, one customer, one team or the whole organization. Memory that spreads an error efficiently is a liability, even when it makes subsequent responses appear more personalized.
Human–agent collaboration and ownership
Multiplayer work should make responsibility clearer. Have one person start a task, another review the evidence and a third receive the handoff. Each person should understand the requested outcome, the current state, the decisions already made and the action waiting for approval. A read-only transcript can be useful documentation, but it does not by itself demonstrate live collaborative control.
Test what happens when two people disagree. An editor might reject a claim while an operator wants to release an approved social post. The system needs a clear authority rule and a visible resolution, not whichever instruction happened to arrive last. Ask whether approvals attach to an immutable version of the proposed action or to a mutable object that can change after review.
The handoff should carry a concise operational summary: what was requested, what was checked, what remains uncertain and who now owns the next step. Preserve the detailed evidence beneath that summary. Requiring every human to reread an entire agent session turns nominal automation into a new review burden and makes errors more likely when the team is busy.
For Sprinklr, inspect the collaboration surfaces included in the quoted plan rather than assuming that unlimited seats means unlimited shared control. For Nagent, ask for a live team room with several authorised people, an approval taken in the Inbox and the audit entry it leaves. In both cases, evaluate notification quality and interruption cost. A system that asks humans to approve every trivial step may be safe but operationally ineffective; one that hides material decisions is difficult to govern.
Governance: inspect the action boundary
Enterprise workflow and governance claims are relevant; test permissions across brands, regions and service queues. [V1] [V2]
The central governance question is what authorizes the system to publish or reply through a brand account. Write the allowed action, the relevant business object, the maximum scope and the approving role in plain language. Then ask the vendor to show where those limits are enforced. Instructions inside a prompt, interface warnings and server-side authorization are different controls and should be documented separately.
Require an inventory entry for each production agent: owner, purpose, tools, data sources, model configuration, permission scope and review date. The same inventory should identify agents that are paused, replaced or awaiting approval. Without that basic record, a team cannot reliably answer who is responsible when an old automation continues running after its original owner has moved on.
A useful audit record links the initiating request, the relevant configuration version, the tool action, any human approval and the resulting business state. Ask for an export that a reviewer can understand outside the vendor interface. A polished activity feed is insufficient if it omits rejected actions, policy decisions or the identity under which a tool executed.
Security credentials also need scope. A certification or audit report can provide important assurance about an organization or service, but it does not prove that your specific agent will follow your refund rule, publishing policy or contact suppression list. Review the relevant report, deployment boundary, data retention and subprocessors while separately testing the business controls. Apply that standard equally to every vendor, whatever its size.
Finally, test emergency stop and access revocation. Remove the agent’s ability to use a test integration, pause a workflow and attempt to resume it with an outdated approval. The expected result should be explicit and recorded. A control is more credible when the team can demonstrate how it fails safely than when it appears only as a checkbox in a procurement questionnaire.
Autonomy, feedback and safe improvement
Autonomy should be granted for a defined task under defined conditions. An agent can be permitted to research freely while still requiring approval to contact a customer or spend money. Avoid a single global label that suggests every action has the same risk. Document what the agent may observe, propose, execute and escalate, and identify the person who can change those permissions.
Nagent's autonomy ladder, L0 Locked to L4 Fully autonomous, ties a visible level to enforced permissions: promotion is offered after approved work, destructive actions always ask first, and demotion follows the Karma record. Ask every vendor for the same three things: the evidence required to promote an agent, the authority that approves it and the conditions that demote it. A visible badge should correspond to actual tool permissions and monitoring behaviour.
For Sprinklr, examine the improvement mechanism appropriate to its product. Updating a prompt, revising a workflow, adding a memory, changing a retrieval source and training a model are distinct operations. A vendor may use one or several. Request a concrete before-and-after example with a change record and a regression check rather than accepting a general statement that the system learns continuously.
Separate production feedback from automatic release. An agent can collect failures and propose an improvement without receiving permission to deploy that improvement itself. Require an evaluation set that includes ordinary cases, important exceptions and previously failed cases. A change should pass the relevant quality and policy gates before it affects a larger audience or gains wider authority.
Monitor for the wrong kind of optimization. A sales agent can increase meetings by lowering qualification standards; a service agent can increase apparent resolution by making escalation harder; a content agent can increase output by repeating material. Pair activity metrics with accepted outcomes, customer impact and human correction effort. The system should learn toward the business objective while preserving the constraints that make that objective acceptable.
Pricing and total cost of ownership
Sprinklr: Enterprise quote. No current numerical suite price verified; modules and service scope vary. [V2]
Nagent: From $29.99 per month. Solo $29.99 per month ($19.99 on annual billing), Team $299 ($199), Business $1,499 ($999), Enterprise by quote. Credits per month are the unit of agent work; Growth Pods add human experts on Business and Enterprise. [N3] Use the live pricing page for current rates, and ask for a scoped quote where a Growth Pod or a Nagent AI Labs engagement is part of the proposal.
Normalize the bill around quality engagement and timely, accurate customer responses. Add subscription or platform charges, model and tool usage, data acquisition, integration work, human review, maintenance and the cost of failed or repeated work. Annual discounts should be shown alongside the commitment required to obtain them. Keep currencies separate unless an explicitly dated exchange-rate assumption is supplied.
Credits are vendor-defined units. A credit can represent an action, a response, an amount of model usage or a generated asset. Two plans that both include ten thousand credits are not necessarily comparable. Request a worked invoice for the exact test workflow, including retries and rejected output. Also confirm whether unused allocations expire, whether overages are automatic and whether a hard cap stops a workflow midway.
The table below sets both list prices side by side for three team sizes. It is a starting point, not a quote: it shows what each vendor publishes for a team of that size, and where a vendor prices on credits, outcomes or consumption it shows that unit rather than guessing your volume. Once a pilot runs, divide the full monthly cost by accepted outcomes; if the denominator is zero, there is no meaningful cost per accepted outcome.
| Monthly cost | A team of 5 | A growth team of 25 | A department of 100 |
|---|---|---|---|
| Nagent | $299 / month Team plan: 10 seats and 6,000 credits a month; $199 a month billed annually | $1,499 / month Business plan: 50 seats and 30,000 pooled credits a month; $999 a month billed annually | By quote Enterprise: unlimited seats, scoped to the work |
| Sprinklr | By quote No public price for a team plan | By quote No public price for a team plan | By quote No public price for a team plan |
- Every figure is a list price from the vendor's own pricing page, before tax and discounts.
- A team total is shown only where the vendor prices per seat or names how many people a plan covers.
- Credits, outcomes and cloud consumption depend on volume, so those vendors show their unit, not a guess.
- Currencies are not converted. Billing period is stated in each cell.
- Nagent's plans were checked on 4 October 2026.
Every vendor at the same three team sizes: AI agent platform pricing compared.
Reviews, customer stories and proof quality
No independent review sample was verified in this research pass. Vendor-hosted testimonials are selection-biased customer evidence, not an aggregate rating.
A useful review is specific about the product, plan, workflow, time period and reviewer’s role. A broad suite review may say little about its newest agent product. An enthusiastic first-day comment may not reveal the burden of maintaining workflows three months later. An isolated negative account is also insufficient to infer that every customer will encounter the same problem.
For both Sprinklr and Nagent, request references whose operating conditions resemble yours: similar workflow complexity, languages, integration stack and human review requirements. Ask what failed during implementation, what still needs manual work and whether the customer would buy the same scope again. These questions produce more decision value than a testimonial that simply says the product saved time.
Customer stories can support a hypothesis, but inspect the denominator behind each metric. Was the improvement measured against a manual process, a previous automation or a selected campaign? Did volume, staffing, audience or media spend also change? Are reported outcomes from the same product version and package being evaluated? Preserve those caveats alongside any quoted result.
This atlas does not manufacture star ratings or infer a consensus from vendor logos. Where access to a review source was limited, that limitation is shown. The next evidence step is a relevant reference conversation and a controlled pilot, not a more confident score built from an incomplete review sample.
Implementation, adoption and exit
Before rollout, identify the smallest workflow that produces a useful result for a real owner. Limit initial inputs to a curated source set and begin with read-only or approval-based actions. This reduces ambiguity during evaluation and makes it easier to distinguish product limitations from bad source material, unclear instructions or missing integration permissions.
Assign responsibility for five ongoing jobs: source quality, workflow design, access administration, output review and incident response. A vendor may perform some of these under a managed service. If so, write them into the agreement with response expectations and escalation contacts. If they remain with the buyer, include the required capacity in the operating budget and adoption plan.
Training should cover the decision process, not only the interface. Users need to know when an agent is proposing a change, when an approval is binding, how to correct a source and how to pause work. A short operating guide for the social lead and customer-care owner is more useful than a large collection of prompts that nobody owns. Give reviewers examples of both acceptable output and cases that require escalation.
Plan the exit while evaluating the entry. Ask whether you can export source mappings, approved prompts, workflow definitions, memory, evaluation cases, run history and final artifacts. Some elements may be proprietary; identify those dependencies honestly. Test that a human can continue the essential process during an outage or after contract termination without losing access to the decisions needed to serve customers.
A practical pilot and acceptance scorecard
Use a staged pilot with a written baseline. First document how the workflow runs today, including volume, cycle time, quality issues and human effort. Select representative examples before the vendor sees them. Include difficult cases and ordinary work, because a pilot made entirely of easy examples produces an unreliable estimate of production performance.
During the first stage, ask both candidates to produce proposals or drafts using the same inputs. Review outputs with a consistent rubric and keep the evaluator unaware of the source where practical. Record factual errors, omissions, policy issues and editing time. Do not average away a serious control failure merely because most outputs are fluent or well formatted.
During the second stage, permit a small set of reversible actions in a test environment or approved pilot scope. Verify resulting business state independently of the agent’s completion message. Introduce a timeout and a repeated trigger to test duplicate prevention. Add a permission change and a rejected approval to observe whether the workflow responds safely.
During the third stage, test real collaboration. Change the human owner, update a source and ask another authorized person to resume the task. Measure the time required to understand the state and make the next decision. This is where shared context should produce value. If the handoff still requires a lengthy explanation outside the platform, include that cost in the result.
Use six scorecard dimensions: factual and output quality; accepted business outcomes; human review burden; authorization and policy behaviour; recovery and traceability; total operating cost. Set thresholds based on your baseline and risk tolerance before the pilot. This guide proposes dimensions, not universal pass percentages. A marketing draft and a customer-account action should not have identical tolerance for error.
At the review meeting, classify each material finding as passed, failed, outside scope or not tested. Attach evidence and name the person who accepts it. A vendor promise to fix a failure is a future commitment, not a passed test. A good decision can be to buy, run a narrower deployment, combine tools or postpone adoption until a missing control is demonstrated.
Questions to take into a vendor review
Specific question for Sprinklr: Can one region’s agent access another brand’s inbox, content library or customer records?
- Show one complete run that ends in an approved social post, including the sources, human decisions and external actions. Which parts are standard and which were specially built for the demonstration?
- Who can change agent instructions, connect a tool, approve an action, view restricted context and export an audit record? Demonstrate these as different roles where the product supports them.
- What happens when a source changes, a user leaves, an integration fails or an agent produces an incorrect result? Which party owns recovery and customer communication?
- Which features in the demonstration are generally available, which require the quoted tier and which remain beta or roadmap items? Put the answer in the commercial scope.
- What is the complete cost at expected and peak usage, and what information can we take with us if we leave?
For Nagent, ask to see a current deployment in your function. The published campaign figures (Emami Navratna: 24.5M+ reach on a single agent-run campaign; Madmonk AI: 5x more qualified leads; Bigbasket: 70% lower video ad production cost; Sophoz: 3x trial user growth after relaunch) are the starting point, and a forward deployed engineer can walk through the implementation plan and the acceptance gate for each custom element.
For Sprinklr, avoid assuming that brand recognition eliminates implementation risk. Ask the team to demonstrate your actual permissions, integrations and exceptions. The evidence threshold should follow the consequence of the action, not the size of the vendor or the polish of its presentation.
Conditional verdict
Sprinklr is broader than a social-writing tool. Its strongest comparison is a coordinated enterprise customer operation, where migration and existing workflow ownership matter. This is a starting judgment for a shortlist, not a procurement endorsement. It should change when a pilot produces stronger evidence. The most useful comparison outcome is a clear account of which candidate can complete the chosen work, under whose control, with what recurring effort and cost.
Choose a Nagent pilot when you want agent teams and people in one workspace, autonomy that is earned and enforced, and a delivery partner that owns the number with you. Require the proof you would ask of anyone: shared context, human control and a safe improvement loop before wider autonomy.
Choose a Sprinklr pilot when its documented product scope matches the immediate job and your team can support its implementation and operating requirements. Consider a combined stack when the specialist, suite or foundation supplies something that a shared workspace should coordinate rather than recreate. In every case, make accepted outcomes and accountable decisions the measure of multiplayer AI.
Frequently asked questions
Is Nagent an alternative to Sprinklr?
Sprinklr is a social publishing, intelligence or care operating layer. Nagent is a multiplayer AI platform where agent teams for marketing, sales and CX work with people in one shared workspace. They overlap where a growth team wants agents to do the work; they differ in operating model, governance and delivery. Many teams run both, with Nagent coordinating the people and decisions.
How does Nagent pricing compare with Sprinklr?
Nagent publishes four plans: Solo $29.99 a month ($19.99 annual), Team $299 ($199), Business $1,499 ($999) and Enterprise by quote, with monthly credits as the unit of agent work. Sprinklr: Enterprise quote. No current numerical suite price verified; modules and service scope vary.
Does Sprinklr offer shared memory and human approvals like Nagent?
Enterprise workflow and governance claims are relevant; test permissions across brands, regions and service queues. Nagent gives every agent one shared memory (Smriti), puts approval before any irreversible action, and keeps an append-only audit trail of every decision.
Which is better for Marketing, CX teams: Nagent or Sprinklr?
Sprinklr is broader than a social-writing tool. Its strongest comparison is a coordinated enterprise customer operation, where migration and existing workflow ownership matter. Nagent fits teams that want agents and people in one workspace, autonomy that is earned from L0 Locked to L4 Fully autonomous, and a forward deployed team that owns the number with them.
What should I ask Sprinklr and Nagent in a demo?
Can one region’s agent access another brand’s inbox, content library or customer records? For Nagent, ask to see a team room with several people, an approval taken in the Inbox and the audit entry it leaves. Measure both on quality engagement and timely, accurate customer responses.
Is Nagent secure enough for enterprise use?
SOC 2 Type II and ISO 27001 programmes underway; tenant isolation, RBAC, append-only audit and private VPC available today. Six workspace roles, per-agent budget caps and a kill switch are standard, and DPDP and GDPR-aligned data handling is built in.
Sources and research notes
- V1 · Official product / pricing source
Sprinklr · product ↗https://www.sprinklr.com/ · Public material checked 21–29 September 2026 - V2 · Official product / pricing source
Sprinklr · commercial / feature reference ↗https://www.sprinklr.com/ · Public material checked 21–29 September 2026 - V3 · Official source
Official Social Publishing platform ↗https://www.sprinklr.com/products/social-media-management/social-media-publishing-platform/ · Public material checked 21–29 September 2026 - V4 · Official source
Official social AI feature availability ↗https://www.sprinklr.com/help/articles/sprinklr-social-specialized-ai-use-cases/sprinklr-specialised-ai-social-features/694159da041df6338a03343e · Public material checked 21–29 September 2026 - N1 · Official source
Nagent · platform, workspace and security ↗https://nagent.ai/platform · Public material checked 21–29 September 2026 - N2 · Official source
Nagent · security and compliance ↗https://nagent.ai/dev-technology/security-and-compliance · Public material checked 21–29 September 2026 - N3 · Official source
Nagent · published plans ↗https://nagent.ai/pricing · Public material checked 21–29 September 2026 - THESIS · Official source
The Nagent Thesis ↗https://nagent.ai/artefacts/nagent-thesis · Public material checked 21–29 September 2026 - GOVERNANCE-SOURCE · Official source
State of Agent Governance ↗https://nagent.ai/artefacts/state-of-agent-governance · Public material checked 21–29 September 2026